How to measure engineering delivery health
Measure delivery health with a small set reviewed as trends, not a scorecard: one throughput metric (deployment frequency or change lead time), one stability metric (change fail rate or failed deployment recovery time) and one team-health signal (review turnaround or PR size), widened only as your own pipeline's measurement data gets reliable enough to trust a fourth or fifth number.
Book a solution review See the related solutionBy Netbase Delivery and Quality Desk · Reviewed by David (CEO) · Updated · 10 min read
This guide is for founders, CTOs, product owners and procurement leads who pay for an outsourced or offshore engineering team and want to know, between releases, whether delivery is actually healthy rather than simply on schedule. Our quality governance pillar introduces DORA's five metrics in brief; this guide goes one layer deeper: which ones to start with at your pipeline's own maturity stage, how to read them from outside the team's daily work, and how a metric gets gamed in a vendor relationship specifically.
In this guide
- Which metric should a team start with?
- A maturity-staged decision matrix
- What a buyer who is not inside the team sees differently
- How a metric gets gamed in a vendor relationship
- A review cadence that uses the numbers
- Where AI fits in measuring delivery health
- What delivery record exists, and what does not
- Alternatives: who owns the measurement
- Limits of this guide
- Frequently asked questions
- Next step
Which metric should a team start with?
The honest answer is "it depends on what your pipeline can already measure reliably," not a fixed list. A team with no CI/CD automation cannot trust a lead-time number pulled from a tool it does not use; a team with mature, automated deployments can support a fuller set without the numbers becoming noise. Start from where your own pipeline already produces trustworthy data, then add one metric at a time.
A maturity-staged decision matrix
| Pipeline maturity | Start with | Add next | Skip until later |
|---|---|---|---|
| No CI/CD, manual releases | Deployment frequency (even a manual count) and a weekly delivery review | — | Change fail rate, cycle-time breakdown, team-health signals |
| Some CI/CD, releases tracked in a ticketing tool | Deployment frequency, change lead time | Change fail rate | Bus factor, after-hours commit patterns |
| Mature CI/CD, automated tests and rollbacks | Deployment frequency, change lead time, change fail rate | Failed deployment recovery time, review turnaround | Deployment rework rate, until the first four are trusted |
Reading the table: a metric that the pipeline cannot yet produce reliably is worse than no metric, because an unreliable number still gets acted on. DORA's own five-metric set (deployment frequency, change lead time, failed deployment recovery time, change fail rate and deployment rework rate) assumes deployments are already instrumented enough to count and time automatically; a team without that instrumentation should build it before trusting the numbers it implies.
What a buyer who is not inside the team sees differently
A founder or CTO who does not sit in the team's stand-ups or review its pull requests cannot pull a dashboard number and trust it on its own; a vendor relationship needs the number plus the context that produced it. Three practices make that possible without the buyer instrumenting anything themselves:
- Ask for the metric as a trend, in the weekly report, not as a one-off screenshot. A single deployment-frequency number tells you little; eight weeks of it, next to the fail rate for the same period, tells you whether speed is coming at the cost of stability.
- Ask what changed the trend, not just what the trend is. A vendor that can explain why change lead time rose two weeks ago (a staffing gap, a dependency upgrade, a client-side approval delay) is reporting honestly; one that cannot explain a shift either is not tracking causes or is smoothing the number before it reaches you.
- Review the metrics at the same cadence as the rest of delivery governance, so they sit next to the demo, the risk list and the decisions you owe the team, rather than arriving as a separate, easy-to-skim artifact. Netbase's own published governance model runs weekly reviews with KPI dashboards, a dedicated account manager and project manager, and client dashboards, inside a six-step delivery lifecycle (discovery, team assembly, agile execution, modular components, rollout, ongoing support); a metrics review that is not anchored to an existing cadence like this tends to drift into an unread PDF.
How a metric gets gamed in a vendor relationship
Every metric on this page can be gamed, and an outsourced relationship has a specific incentive problem a co-located team does not: the vendor is paid or renewed partly on how the numbers look, which rewards the appearance of health over the substance of it. Watch for these patterns specifically:
- Deployment frequency inflated by splitting trivial changes. Ten tiny deploys of one feature is not ten times healthier than one deploy of it; ask what shipped, not only how often.
- Change fail rate held low by widening what counts as "failed." If a rollback is quietly reclassified as a "planned update," the rate looks better while nothing improved; ask for the raw incident list behind the percentage.
- Lead time shortened by moving work out of the measured pipeline. Work that moves to an informal channel before the ticket opens does not make the real lead time shorter, only the measured part of it.
- A team-health signal used as a second scorecard. Review turnaround or PR size exists to explain why a delivery metric moved, not to rank individual engineers; a vendor that reports it that way has misread its purpose.
The fix in every case is the same one DORA's own research recommends: treat the numbers as a diagnostic thermometer that prompts a question, never as a target a contract is written against.
A review cadence that uses the numbers
-
Confirm what the pipeline can already measure reliably
, using the maturity table above, before adding a metric that sounds right but cannot yet be trusted.
-
Put the chosen metrics in the same weekly report as the demo, risk list and open decisions
, so they are read in context rather than skimmed alone.
-
Review trends over four to eight weeks, not single values
, since one bad week in a healthy pipeline looks the same as one good week in an unhealthy one.
-
Ask what changed whenever a trend moves
, and treat "nothing, it's just noise" as an answer that needs its own follow-up once.
-
Add the next metric only after the current set has been trusted for a full review cycle
, rather than adopting a full DORA-plus-SPACE dashboard on day one.
-
Revisit the set when the engagement model changes
(a new feature stream, a different release cadence, more or fewer engineers), since a metric set sized for one phase of a project can mislead in the next.
Where AI fits in measuring delivery health
AI is useful for turning raw pipeline data into a readable trend faster, never as the judge of whether a number is good or bad. Netbase works with the major commercial and open-source AI models, chosen per project.
-
In delivered work
Product recommendation engine
Built for 4over4's online printing store from browsing and purchase history; a commerce feature, not a delivery-metrics tool, shown here as Netbase's named delivered-AI proof.
-
Available capability
AI-assisted trend summarisation
Drafting a plain-language summary of why a delivery metric moved, from the same data a dashboard already shows, is a generative AI and analytics feature; not yet tied to a published delivery-metrics case.
What delivery record exists, and what does not
Netbase has not published a delivery-health dashboard or metric history for a named client, and does not claim one. What is published:
- Governance practice. Netbase's own published delivery model runs weekly reviews with KPI dashboards, a dedicated account manager and project manager, and client dashboards, Slack or Zoom communication, inside a six-step lifecycle from discovery to ongoing support; teams of 3 to 30 combine business analysts, project managers, solution architects, developers, QA and UI/UX, typically starting within one to two weeks of discovery. Delivery covers Agile increments with weekly reviews as a stated practice.
- Security as one input signal. Secure code review, vulnerability scanning and penetration testing, role-based access and MFA for admin dashboards are Netbase's published security practices; they are an input to delivery health (a late-caught vulnerability shows up as an unplanned change), not a delivery metric themselves.
- Two commerce engagements with published release-linked figures. For USticker, Netbase delivered an e-commerce payment enhancement with reported results of conversion up 40% for design-tool users, completed designs up 32% in six months, retention up 25%, online-order revenue up 15% and page load time down 21%. For PrintLeo, the published results are engagement up 25%, online sales revenue up 20%, bounce rate down 40%, page load improved 35% and order processing time down 15%. Neither record publishes a DORA-style deployment or lead-time number; they show the business outcomes a release-linked metric set should ultimately protect.
What does not exist. No published Netbase record states a deployment frequency, change lead time, change fail rate or recovery-time figure for any engagement, and none is invented here. The maturity matrix and gaming patterns above come from public DORA and engineering-practice research applied to a buyer-governance problem, not from a measured Netbase project.
Alternatives: who owns the measurement
| Route | Strength | Choose it when |
|---|---|---|
| The buyer instruments the pipeline directly | Full control over definitions and raw data | You have engineering capacity to run the tooling yourself, typically for an in-house or hybrid team |
| The vendor reports metrics from its own tooling | No extra tooling cost to the buyer | You trust the vendor's governance cadence and ask for raw incident lists, not only percentages |
| A dedicated engineering-analytics platform | Automated collection across issue trackers and version control, less manual reporting | Volume and team size justify the tool cost, usually past a few concurrent engineers |
Most Netbase projects are delivered on fixed-price contracts agreed after discovery, with milestone-based, monthly team retainer and KPI-linked terms also offered where they fit the engagement better; in every model, the governance cadence above is how a buyer gets delivery-health visibility without instrumenting anything themselves.
Limits of this guide
- The maturity matrix is a reasoned framework, not a benchmark derived from a measured Netbase dataset.
- DORA and SPACE are cited for what they define; no claim is made that any Netbase project conforms to a stated benchmark tier.
- No deployment, lead-time, cycle-time or defect-rate figure is published for a Netbase engagement; the USticker and PrintLeo figures are the engagements' own published business results, not delivery-pipeline metrics.
Plan the next step with a Netbase consultant
Frequently asked questions
Deployment frequency, even counted manually from release notes, because it needs no new tooling and still shows whether releases are happening at a steady, sustainable pace.
Treat a benchmark as a rough reference, not a pass/fail line; product risk, release size and how "failure" is defined vary enough between teams that a single threshold rarely means the same thing twice.
Yes, because team-health signals like review turnaround and PR size often move before delivery metrics do; healthy-looking output today can still be running on an unsustainable pattern that shows up as a decline next quarter.
Rarely week to week; review trends over four to eight weeks and reserve a decision (adding capacity, revisiting scope, raising a risk) for a sustained shift, not a single data point.
Next step
Tell us what your pipeline can already measure today, and we will book a solution review to size a metric set your own data can support. You can also read the quality governance pillar or browse more Netbase insights.
Work behind this guide
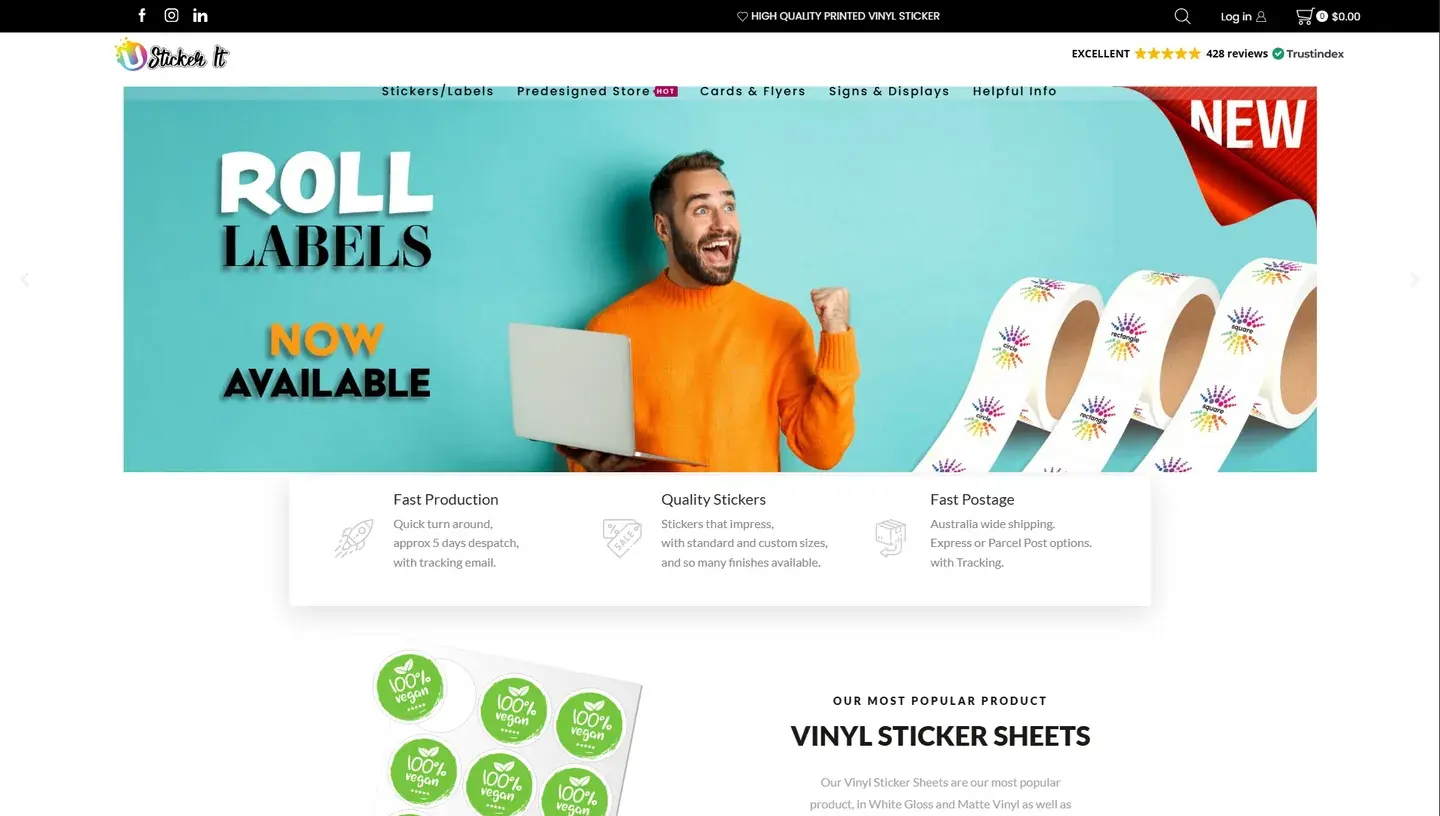
Design-tool users converted 40% more often, and online-order revenue rose 15%.
Keep ReadingRelated services and solutions
 AI-assisted QA and software testing that run inside delivery
Netbase provides software testing and QA services for product and commerce teams to release often without breaking what customers use. QA runs inside delivery, not after it: acceptance criteria, automated regression with AI-generated test drafts, performance budgets and release readiness checks. Page speed shows the result: USticker's page load fell 21%, and PrintLeo's improved 35%.
Learn More
 Web-to-print platform with AI design assistance, from online design to a print-ready order
A web-to-print platform is an online ordering, design and prepress workflow that helps print businesses sell custom products: customers configure, design and approve their order online, AI can suggest layouts and catch artwork problems, and production receives a print-ready file. Netbase has delivered 50+ custom web-to-print platforms across apparel, packaging, signage, promotional merchandise and corporate B2B portals.
Learn More
Work with Netbase remotely
Every Netbase engagement is delivered remotely, so clients in any country and any industry can work with us; Netbase has worked with clients in 80 countries. Contracts and invoices are issued by Netbase JSC, and payment is made by bank transfer to Netbase JSC's company account or PayPal Business. Talk to the CEO, Huy Nguyen (David), on WhatsApp or by email.
Discuss a project
Netbase JSC helps organizations design, build, modernize, and operate digital products and AI-enabled business systems.project@netbasejsc.com
+84 937 869 689
91 Nguyen Chi Thanh, Dong Da, Hanoi, Vietnam
Get in touch
Tell us what you want to build, modernize, or operate.